Frontier AI models from flash — no GPU queue, no HBM
NANDmind is an inference accelerator in development. It keeps giant mixture-of-experts models in NAND flash and streams only the experts each token needs. Designed for 600B–3T-parameter models.
Why flash, why now
Only the experts you need.
A mixture-of-experts model uses a small share of its weights for each token: DeepSeek-V3 activates 37B of its 671B parameters. NANDmind reads only those experts, from many flash channels at once.
Capacity without HBM.
Flash costs a small fraction of HBM per gigabyte, so the whole model lives on the board instead of in scarce GPU memory.
No GPU queue.
Built from parts you can buy today — NAND flash and FPGAs, with a custom chip later. Add capacity without waiting for a GPU allocation.
Who it is for
How it works
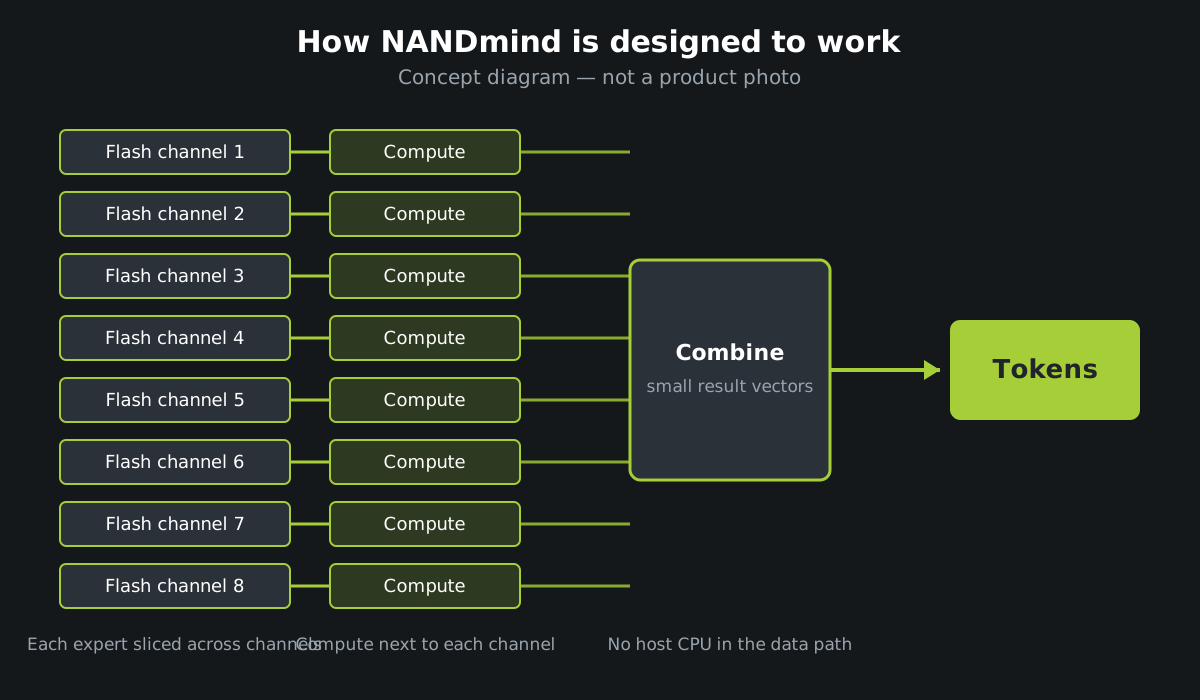
Every expert is sliced across many independent flash channels, with compute next to each channel. When the model picks experts for a token, all channels read their slices in parallel. No host CPU, file system or flash translation layer sits in the data path, and hot experts are copied across channels to balance load and spread wear.
Design targets
600B–3T parameters
Designed for the largest open mixture-of-experts models, from DeepSeek-V3-class (671B) to 3T parameters. Bigger models take more modules.
Private by design
Run a frontier-class model in your own server room. Weights, prompts and outputs stay on your hardware.
Lower cost per token
Flash is cheap per gigabyte, and read bandwidth grows with the number of channels. We target a lower cost per token than GPU servers for MoE inference; our estimates are on the Configurations page.
A second source of capacity
Inference capacity that does not depend on GPU allocations or HBM supply — for batch jobs, evaluations, synthetic data and private deployments.